Egress service failures
Incident
Report for LiveKit
Postmortem
Outage Causes
Trigger
-
We started receiving a rapid spike of StartEgress in one of our clusters. The request rate was 10x of what we typically receive
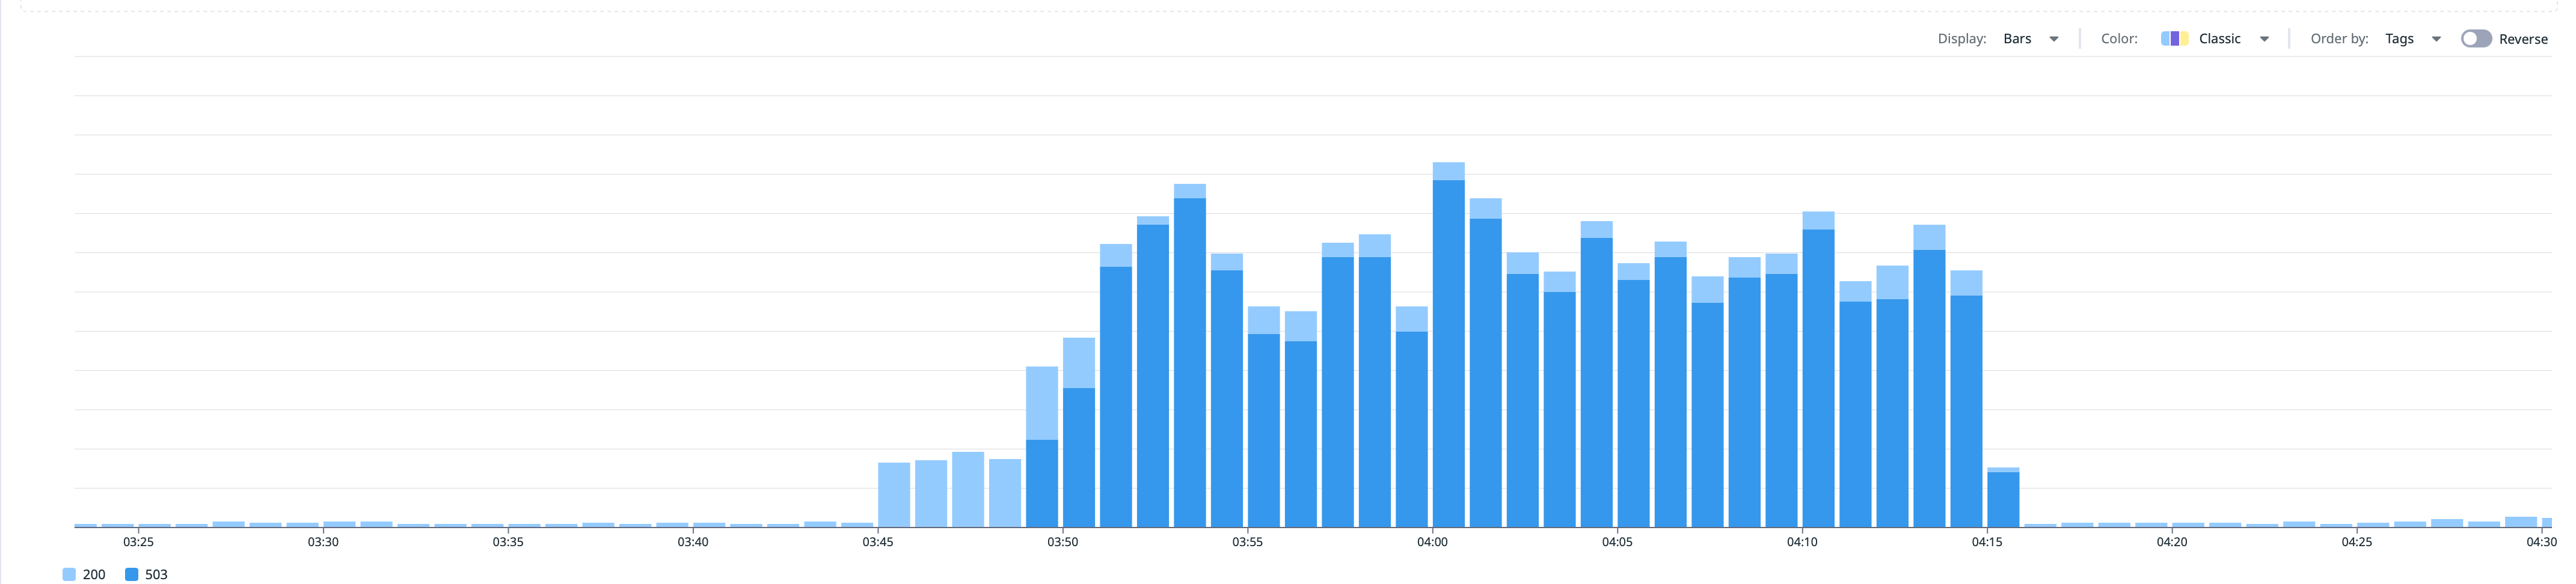
Our infrastructure is setup with some amount of idle egress instances to absorb extra requests. This amount was tuned for the typical egress request pattern.
Fallout
- The egress pods with extra capacity started accepting the new requests. The autoscaler started bringing up new pods as needed to keep the idle pod count on target. The rate of new pod creation was thus limited by the target idle pod count. The pods were allocated from a pool of warm nodes available to absorb request bursts in either the Egress or cloud-media clusters.
- After 4 min the infrastructure ran out of warm nodes and started provisioning new nodes from our cloud provider. Node provisioning takes several minutes and was only done a few nodes at a time because of the aforementioned scaling algorithm.
- The Egress API started returning 503 errors to a percentage of new API requests. Existing egresses were not affected.
- After 25 min, the cluster had started enough new pods to absorb the peak in Egress requests. This was the end of the customer impact
Contributing factors
- The alert threshold for API error rate for Egress were misconfigured, delaying notification and escalation of the issue.
- The size of the warn node pools was too small for this cluster.
Remediation
- The algorithm used to compute the target amount of idle Egress pods has been modified to keep a significantly larger buffer, in order to be able to absorb greater traffic spikes.
- Alerts threshold were changed to provide a quicker escalation of 503 errors in the Egress API.
- We are working on adjusting the size of the warm node pool.
Resolved
At 10:50 UTC, we identified a high rate of failures caused by 503 errors on the Egress service affecting some of our customers. Other services were not impacted. This was caused by a large unexpected spike in egress requests overwhelming our capacity to scale up our Egress cluster quickly.
The issue has been resolved around 11:20 UTC
The issue has been resolved around 11:20 UTC